Llmxray
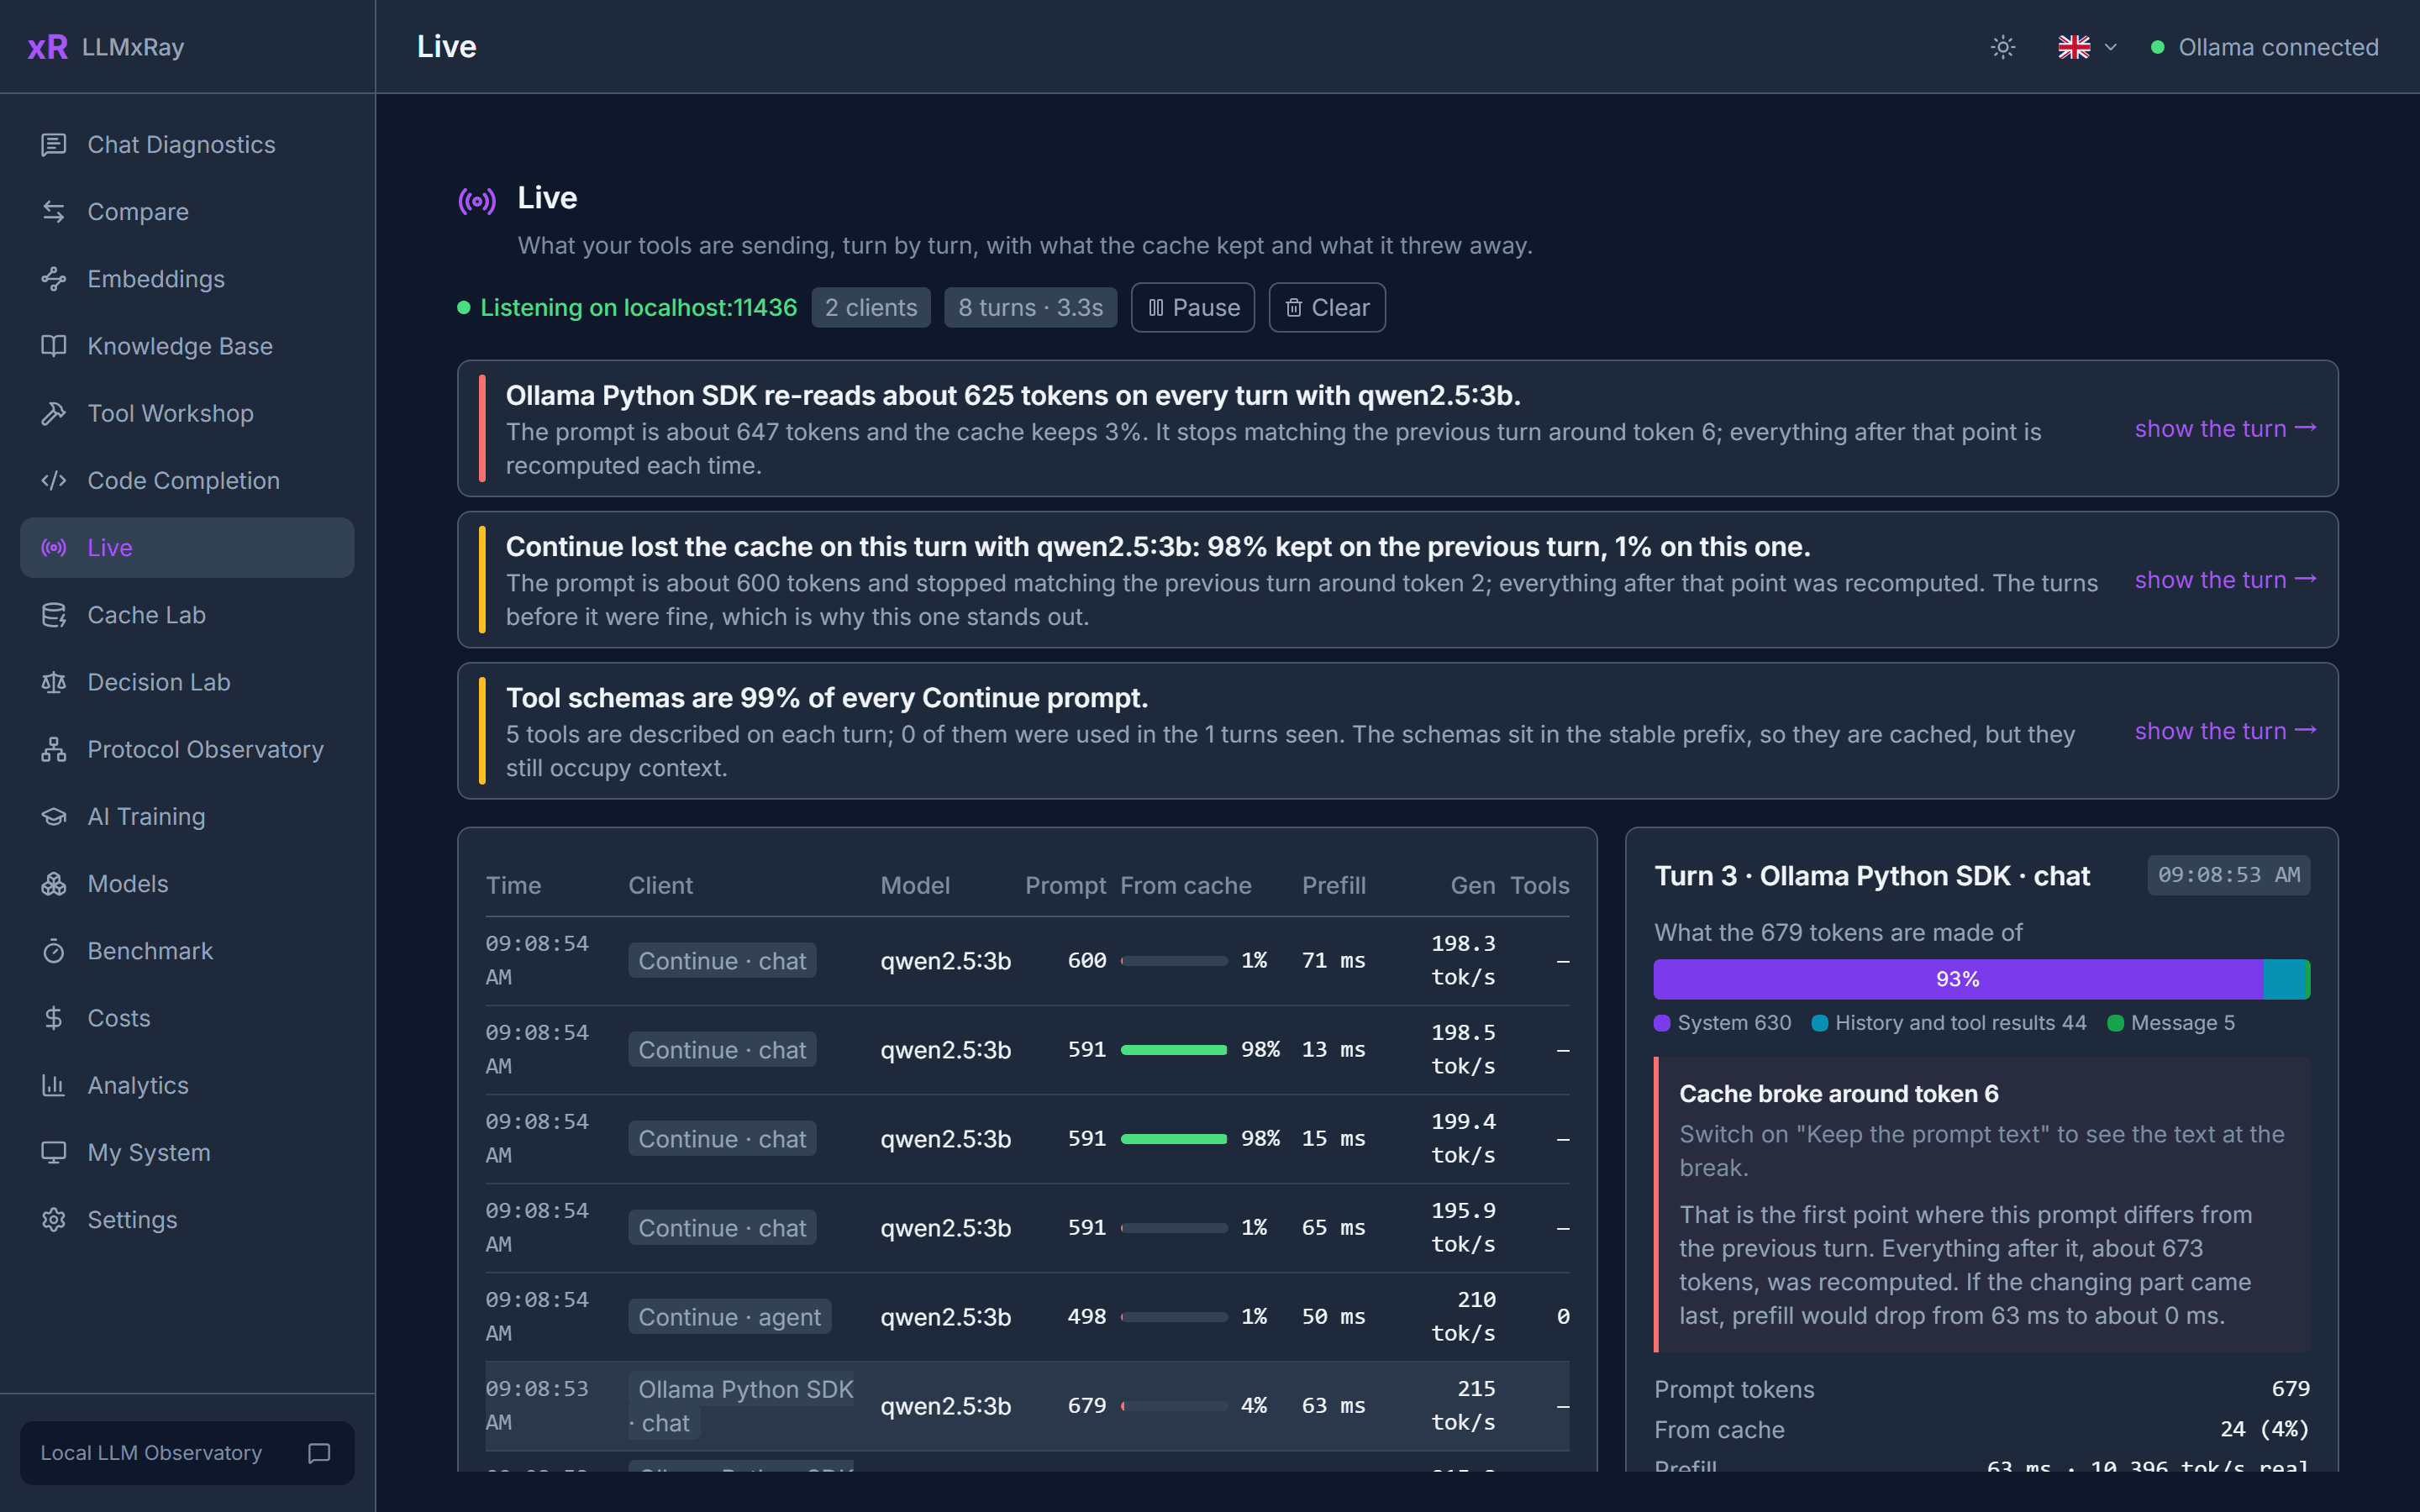
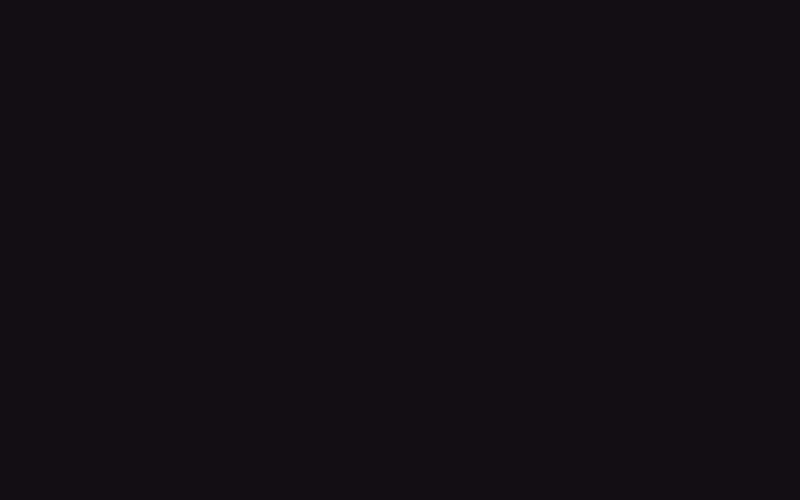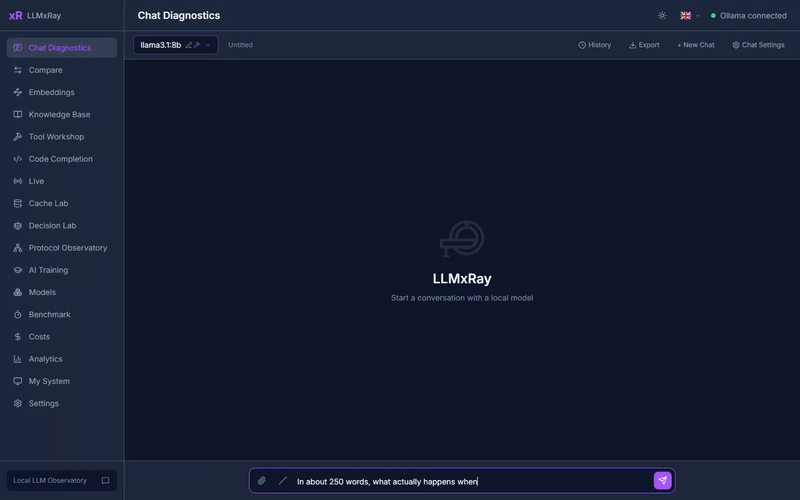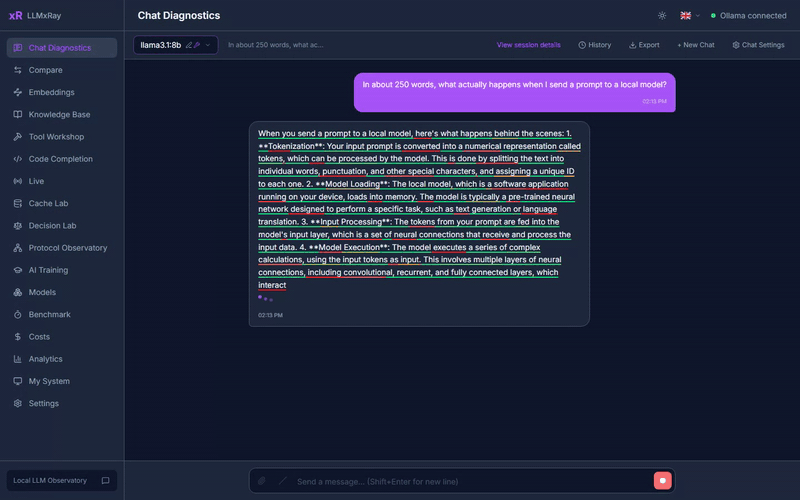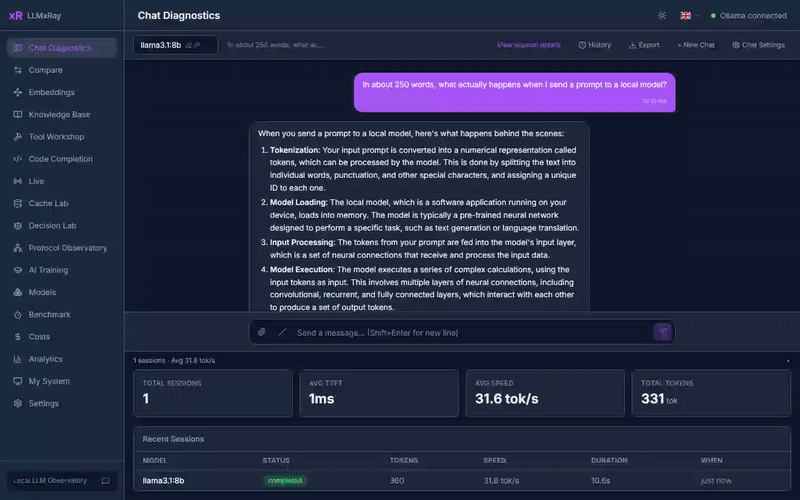
LLMxRay — Local LLM Observatory. Full observability interface for Ollama: chat, streaming, reasoning, RAG, introspection, metrics.
1 / 4
About
See what your local AI is actually doing.
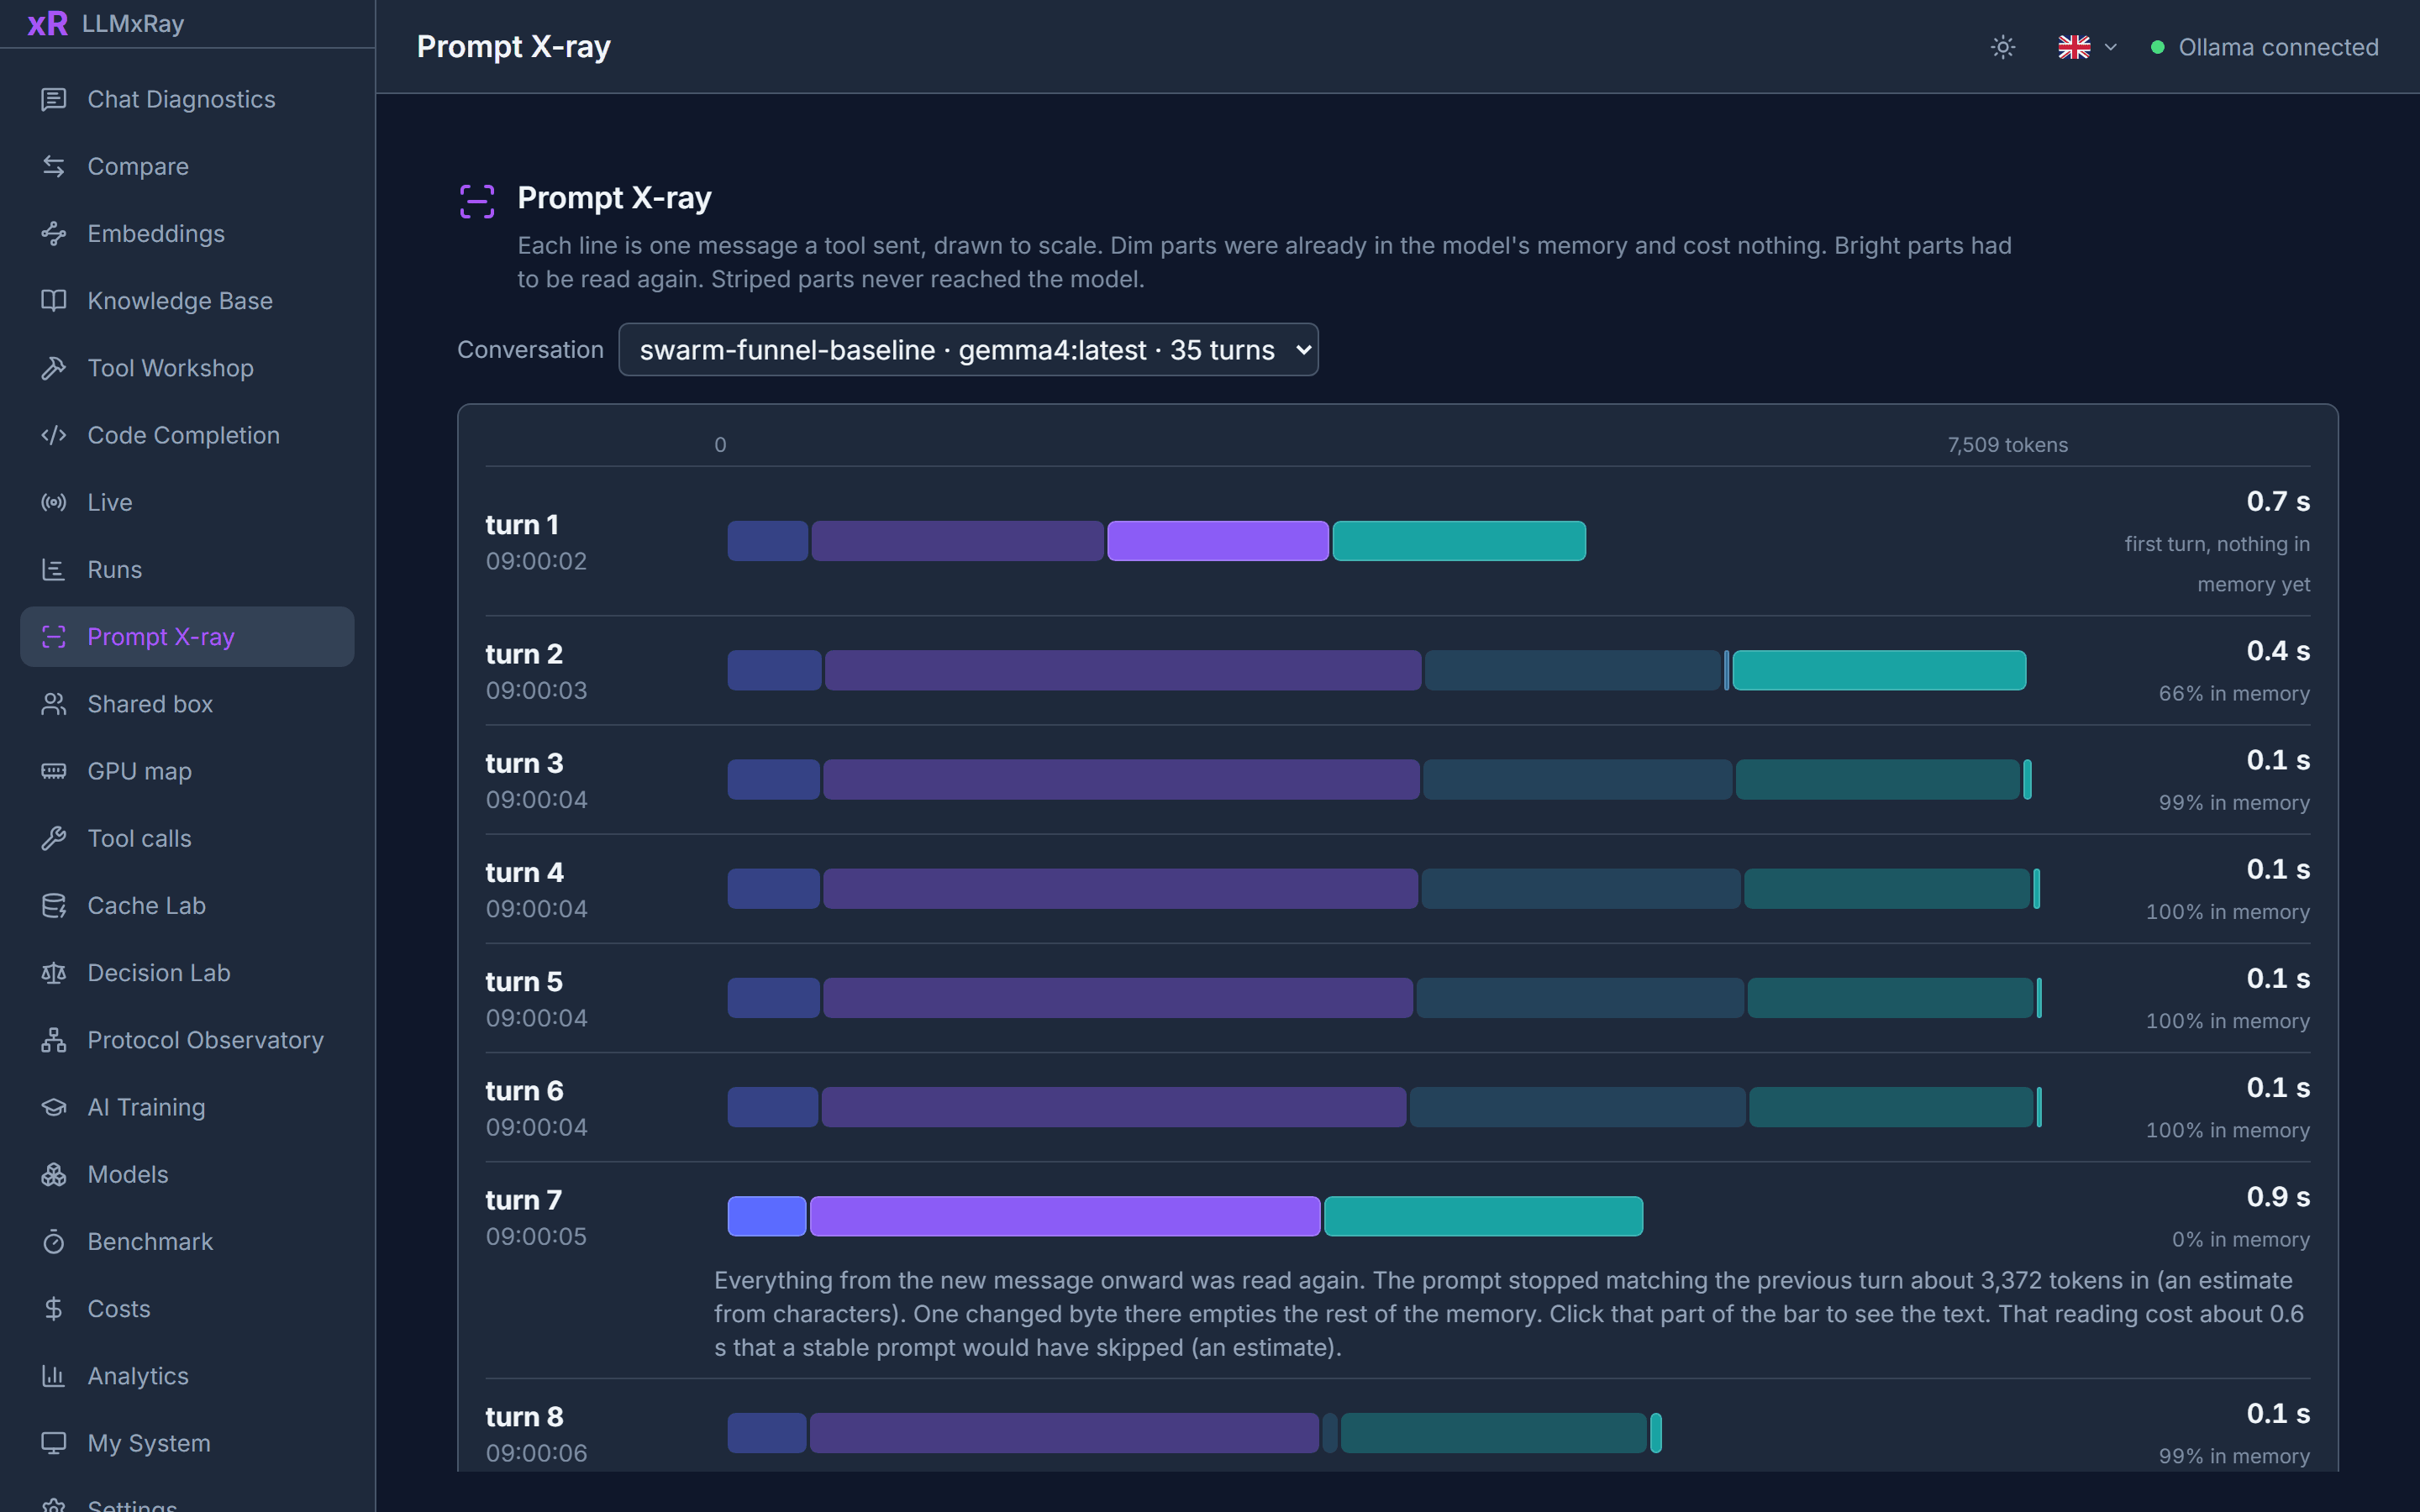
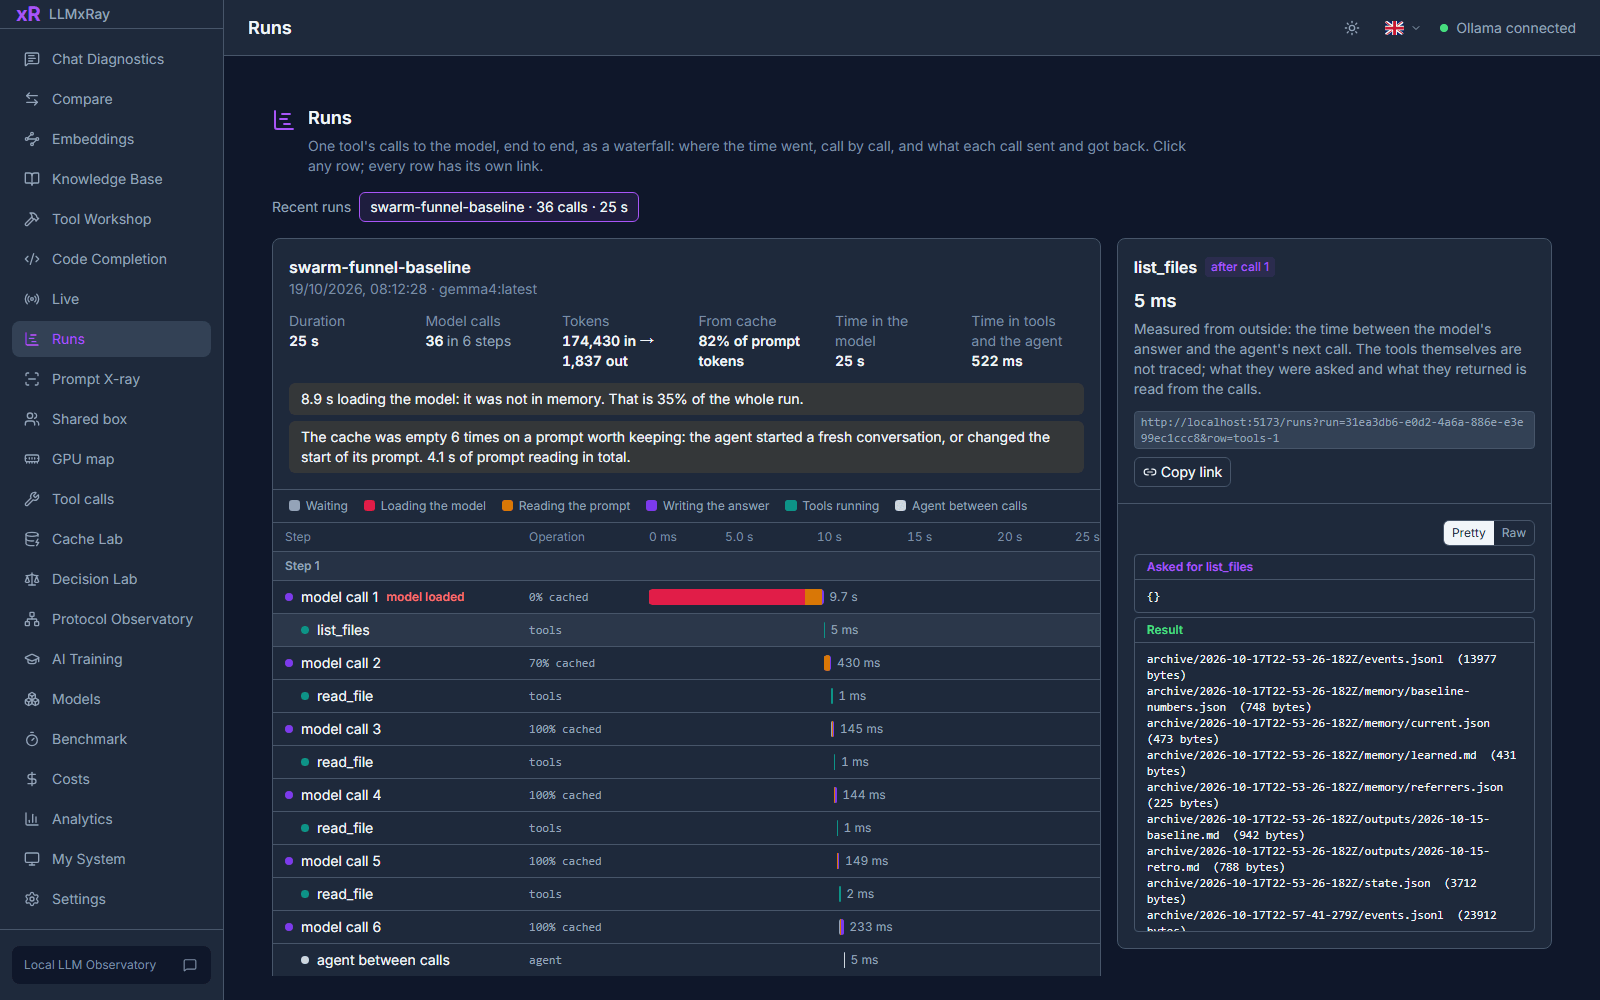
Point VS Code Copilot, Open WebUI, Continue, n8n or your own agent at LLMxRay instead of Ollama, and see every turn: what was cached, what was read again, what the daemon silently cut, which tool evicted which model. No cloud. No API keys. No cost.
You need Ollama running with at least one model pulled (ollama pull llama3.2). Then:
How it was made
Estimated by the maker.